Backtest bias: validate a trading strategy without hindsight · 4 / 5
Keep the losing trials in a parameter search
The best result of a search is not the same experiment as a rule fixed before the data were observed. A truthful research record includes the alternatives that lost.
Athenum7 minUpdated:
Parameter optimization: record every trial in a ledger
Five lookbacks, four entry thresholds and three exits create sixty configurations on the same history. Suppose the best net total is +18R while the median is −2R. The winning arithmetic can be correct while providing weak evidence of a persistent advantage: the process was designed to choose an extreme result.
Store parameters, data version, interval, costs, exclusions, selection metric and results for every trial. Asset changes, deleted months, new timeframes and alternative performance metrics also alter the search. A final script rarely records those discarded decisions, so preserve a separate experiment ledger.
Multiple testing: trials on shared data are not independent
For a toy calculation only, sixty independent null tests with a 5% false-positive probability each have probability 1 − 0.95^60 ≈ 95.39% of at least one false positive. This does not measure the probability that the selected strategy is false. Shared observations make parameter trials dependent, and no hypothesis test was specified for the +18R example.
Inspect neighbouring parameter values and individual influential trades. An isolated peak deserves scrutiny, but does not alone prove a bug. A broad stable neighbourhood is useful sensitivity evidence, not a substitute for evaluation on observations that did not shape the search.
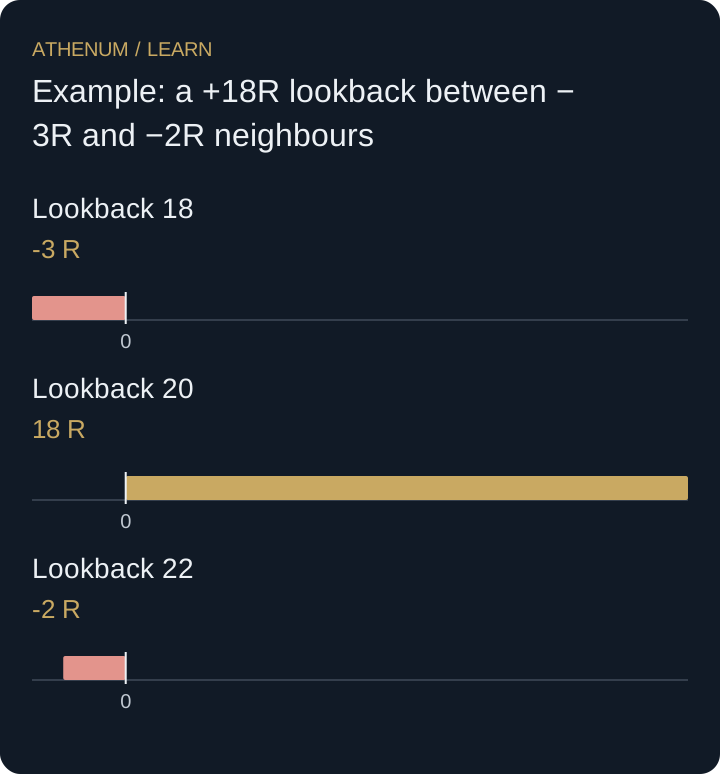
Example: a +18R lookback between −3R and −2R neighbours
Three neighbouring lookbacks produce −3R, +18R and −2R under otherwise identical hypothetical assumptions. Preserve all three results. Check whether a small number of fills, a boundary convention or a data anomaly explains the peak before proposing a causal story.
The original grid has 5 × 4 × 3 = 60 configurations. Recording two predeclared cost scenarios gives 120 configuration/scenario rows. Those rows are not 120 independent tests. Selecting the cheaper cost model because it makes the winner look better is another research choice that must be disclosed.
| Lookback | Net total |
|---|---|
| 18 | −3R |
| 20 | +18R |
| 22 | −2R |
 Open full-size diagram
- Lookback 18: -3 R
- Lookback 20: 18 R
- Lookback 22: -2 R
Mistake: using a robustness check to pick the published rule
Calling a second pass a robustness check does not make it independent if its result determines which rule you publish. Predeclare the role of each scenario, and retain failed runs rather than quietly dropping them from the denominator.
Before acting
- Retain every configuration and result.
- Record changes outside the parameter grid.
- Separate stress scenarios from selection criteria.
- Inspect neighbouring values and influential trades.
- Reserve unseen data before searching.
Check your understanding
You double the original five lookbacks to ten, keeping four thresholds, three exits and two cost scenarios. How many rows are recorded, and are they independent?
Show the explained answer
There are 10 × 4 × 3 × 2 = 240 configuration/scenario rows. They are not automatically independent: they share market observations and many rule components. Row count documents the search; it does not establish an effective independent sample size.
Sources and further reading
Continue with Athenum
From the Athenum blog
Perpetual Futures Survivorship Bias: 172 of Bybit's 571 One Year Contracts Are Already Gone
Related lessons
- Trading bootstrap: preserve dependent blocks when resampling results
Resampling single trades breaks a shared daily shock. Enumerate a trade-versus-day bootstrap and see why ten thousand resamples are still two observed days.
- Audit the denominator behind a chart-pattern success rate
One hundred candidates, sixty entries, twenty-four wins. Separate candidates, qualified entries, target touches and profitable trades before quoting a rate.